Phenotypic Profiling & Screening, Ardigen phenAID
Turn Cell Painting and high-content imaging into phenotypic profiles for hit prioritization, MoA analysis, toxicity profiling or virtual screening.
Ardigen phenAID: an end-to-end solution for phenotypic drug discovery
Ardigen phenAID turns complex measurements into interpretable, comparable signatures that inform drug discovery decisions.
The platform generates high-dimensional representations from high-content imaging, chemical structures and multi-omics data, then integrates them into a coherent, model-ready system.
Multimodal data product in an AI-native data platform
Ardigen phenAID integrates
- data sourcing, ingestion and harmonization
- multimodal data processing and FAIRification
- modeling, prediction and insight generation
- feedback from new experimental data into subsequent analysis cycles
A high-resolution view of phenotypic change
Identify signatures associated with mode of action, bioactivity and off-target effects.
Analyze cellular responses and detect patterns across chemical or genetic perturbations.
Compare perturbations at scale and group compounds or genes by shared phenotype.
Combine image-derived profiles with omics data to connect molecular mechanisms with phenotype.
Unified predictive layer that turns comparable phenotypes into confident project decisions.
AI phenotypic modeling
Reproducible, versioned pipelines combine handcrafted and deep-learning representations, with new experimental data incorporated into later analysis iterations.
Batch-effect correction
Methods are matched to the experimental design and assessed with quality metrics to reduce technical variation while preserving biological signal.
Multivariate analysis
Models evaluate multiple biological properties together to support compound and perturbation comparison.
Multimodal integration
Image-derived phenotypes are linked with chemical structures and genomic, transcriptomic, proteomic or other available omics layers.
Engineering for scalable phenotypic discovery
Secure cloud and on prem deployment
Flexible infrastructure that runs where your data governance requires, with the same reproducible pipelines across environments.
Scalable data management
Storage and retrieval built for high-dimensional feature sets, supporting similarity search, compound clustering, and cross-experiment comparison at program scale.
Workload orchestration.
Intelligent scheduling of inference workloads across the available computing resources, so every AI model runs where it fits best and no capacity sits idle.
AI model versioning and retraining
Managed model lifecycle from first training run through the AI–lab loop, where new experimental results retrain and sharpen the models, with full lineage at every step.
Experiment tracking and reproducibility
A complete, queryable record of every experiment, so results can be reproduced, compared, and trusted across your organization.
Monitoring and observability
- Continuous visibility into model and pipeline health, catching drift and failures before they reach your results.
Contact us for the a demo consultation
A proud partner of the JUMP-CP Consortium
Ardigen is a key supporter of the JUMP-CP Consortium, which aims to validate and scale up image-based drug discovery strategies by creating the world’s largest public cell imaging dataset, encompassing both genetic and chemical perturbations.
The consortium’s members include 10 leading pharmaceutical companies (Amgen, AstraZeneca, Bayer, Biogen, Eisai, Janssen Pharmaceutica NV, Merck KGaA, Pfizer, Servier, and Takeda), along with two non-profit research organizations (the Broad Institute of MIT and Harvard), and Ksilink.
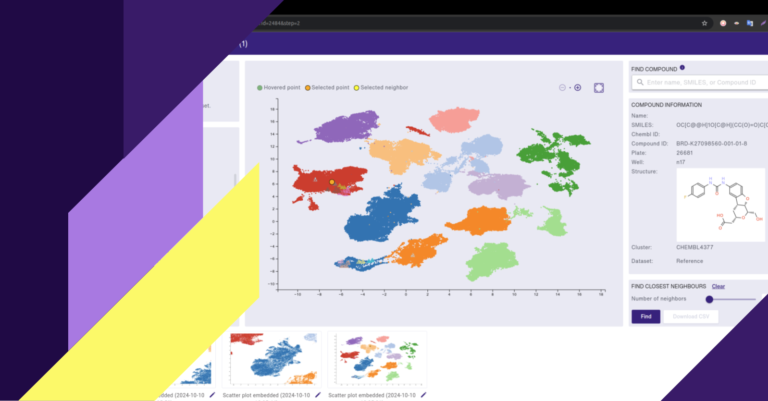
Ardigen contributes deep learning expertise and provides a web application to facilitate the exploration of the JUMP-CP Cell Painting dataset and advance cell pointing say analysis.
Visit our Knowledge Hub to read more about
Phenotypic Profiling

Frequently Asked Questions
What is phenotypic screening in drug discovery?
Phenotypic screening tests compounds based on the effect they produce in a biological system rather than on a predefined molecular target. It can capture complex cellular responses and identify active compounds when the underlying target or mechanism is not yet known.
Is Ardigen phenAID a SaaS platform or a custom implementation?
Neither, exactly – Ardigen phenAID is deployed as a customized platform implementation, not a generic SaaS subscription. It comes with standardized architecture for data ingestion and feature extraction, and AI models for MoA and bioactivity prediction, hit identification, and virtual screening. Each implementation is then configured to the client’s needs and requirements.
Does Ardigen phenAID generate handcrafted features or deep learning embeddings?
Both. CellProfiler is integrated into Ardigen phenAID for handcrafted features, alongside our proprietary deep learning model for image-based embeddings. You can choose which to include in the analysis workflow.
What data does Ardigen phenAID require to get started?
The core input is Cell Painting or high-content screening image data with associated compound identifiers and experimental metadata. Chemical structures (SMILES or similar) are required only for virtual screening. Omics data (transcriptomics, proteomics) can be integrated for multimodal analysis but isn’t a prerequisite.
Ardigen assesses data readiness at the start of an engagement and identifies any gaps before platform configuration begins.
How does Ardigen phenAID use JUMP-CP data?
JUMP-CP is the largest publicly available Cell Painting dataset, covering over 116,000 compounds with matched morphological profiles. We used it to pre-train our AI models. We can also align proprietary screening data to JUMP-CP representations, enabling cross-dataset compound comparison and extending phenotypic context beyond your own data
What is the AI–lab loop, and how does it work in practice?
The AI–lab loop is the feedback mechanism that connects Ardigen phenAID’s computational predictions to experimental results. When compounds prioritized by the virtual screening module are tested in the lab, those outcomes are returned to the platform and used to refine and retrain the underlying models.
Prediction quality improves as experimental data accumulates – the platform becomes more accurate as a discovery program progresses.
Can Ardigen phenAID integrate with our existing informatics and data infrastructure?
Yes. Data and infrastructure integration is core to the platform, and Ardigen’s data engineering capabilities are included. Integration with existing ELN systems, compound management databases, and imaging platforms is scoped during the implementation design phase.
What data can be used in a phenAID project?
A project can start from high-content or Cell Painting images and may incorporate chemical structures, assay annotations, reference profiles and relevant omics data. The final input set depends on the scientific question and the data available.
Contact
Discuss your phenotypic screening use case
Share your assay, imaging data and the decision you need to make. We will review the available inputs and define an appropriate Ardigen phenAID analysis or integration scope.
Newsletter
Become an insider
Be the first to know about Ardigen’s latest news and get access to our publications, webinars and more!