Knowledge graph implementation for life sciences R&D
Move fragmented biomedical data into operational knowledge infrastructure
A knowledge graph alone creates limited value.
Your organization may already have a knowledge graph, a licensed biomedical knowledge base, proprietary datasets, or a promising proof of concept. Yet scientists still move between disconnected databases, manual analyses, and specialist tools. Internal assets remain separated from broader biological context, and every new question creates another integration project.
That gap has a cost: graph and data investments are difficult to justify, scientific teams do not adopt the infrastructure, and potentially valuable target, indication, or repurposing relationships remain harder to explore. Downstream AI systems also lack the structured, traceable context needed for reliable scientific use.
From knowledge graph PoC to a production-ready system
Turn knowledge graphs into usable R&D capabilities, from use-case definition and data readiness through deployment, scientific adoption, and ongoing operations. Extend an existing graph, operationalize an acquired knowledge base, or build on a suitable public foundation with cross-functional expertise across drug-discovery biology, semantic and data engineering, graph analytics, machine learning, and scientific software development.
What changes
Proprietary evidence becomes connected to public biomedical context.
Scientific questions become repeatable graph-based analyses and workflows
Researchers access results through appropriate applications, APIs, analytics, or interfaces
Data updates, performance, quality, and new use cases become part of an operating model
The solution remains in your environment, with your data, hypotheses, and models under your control
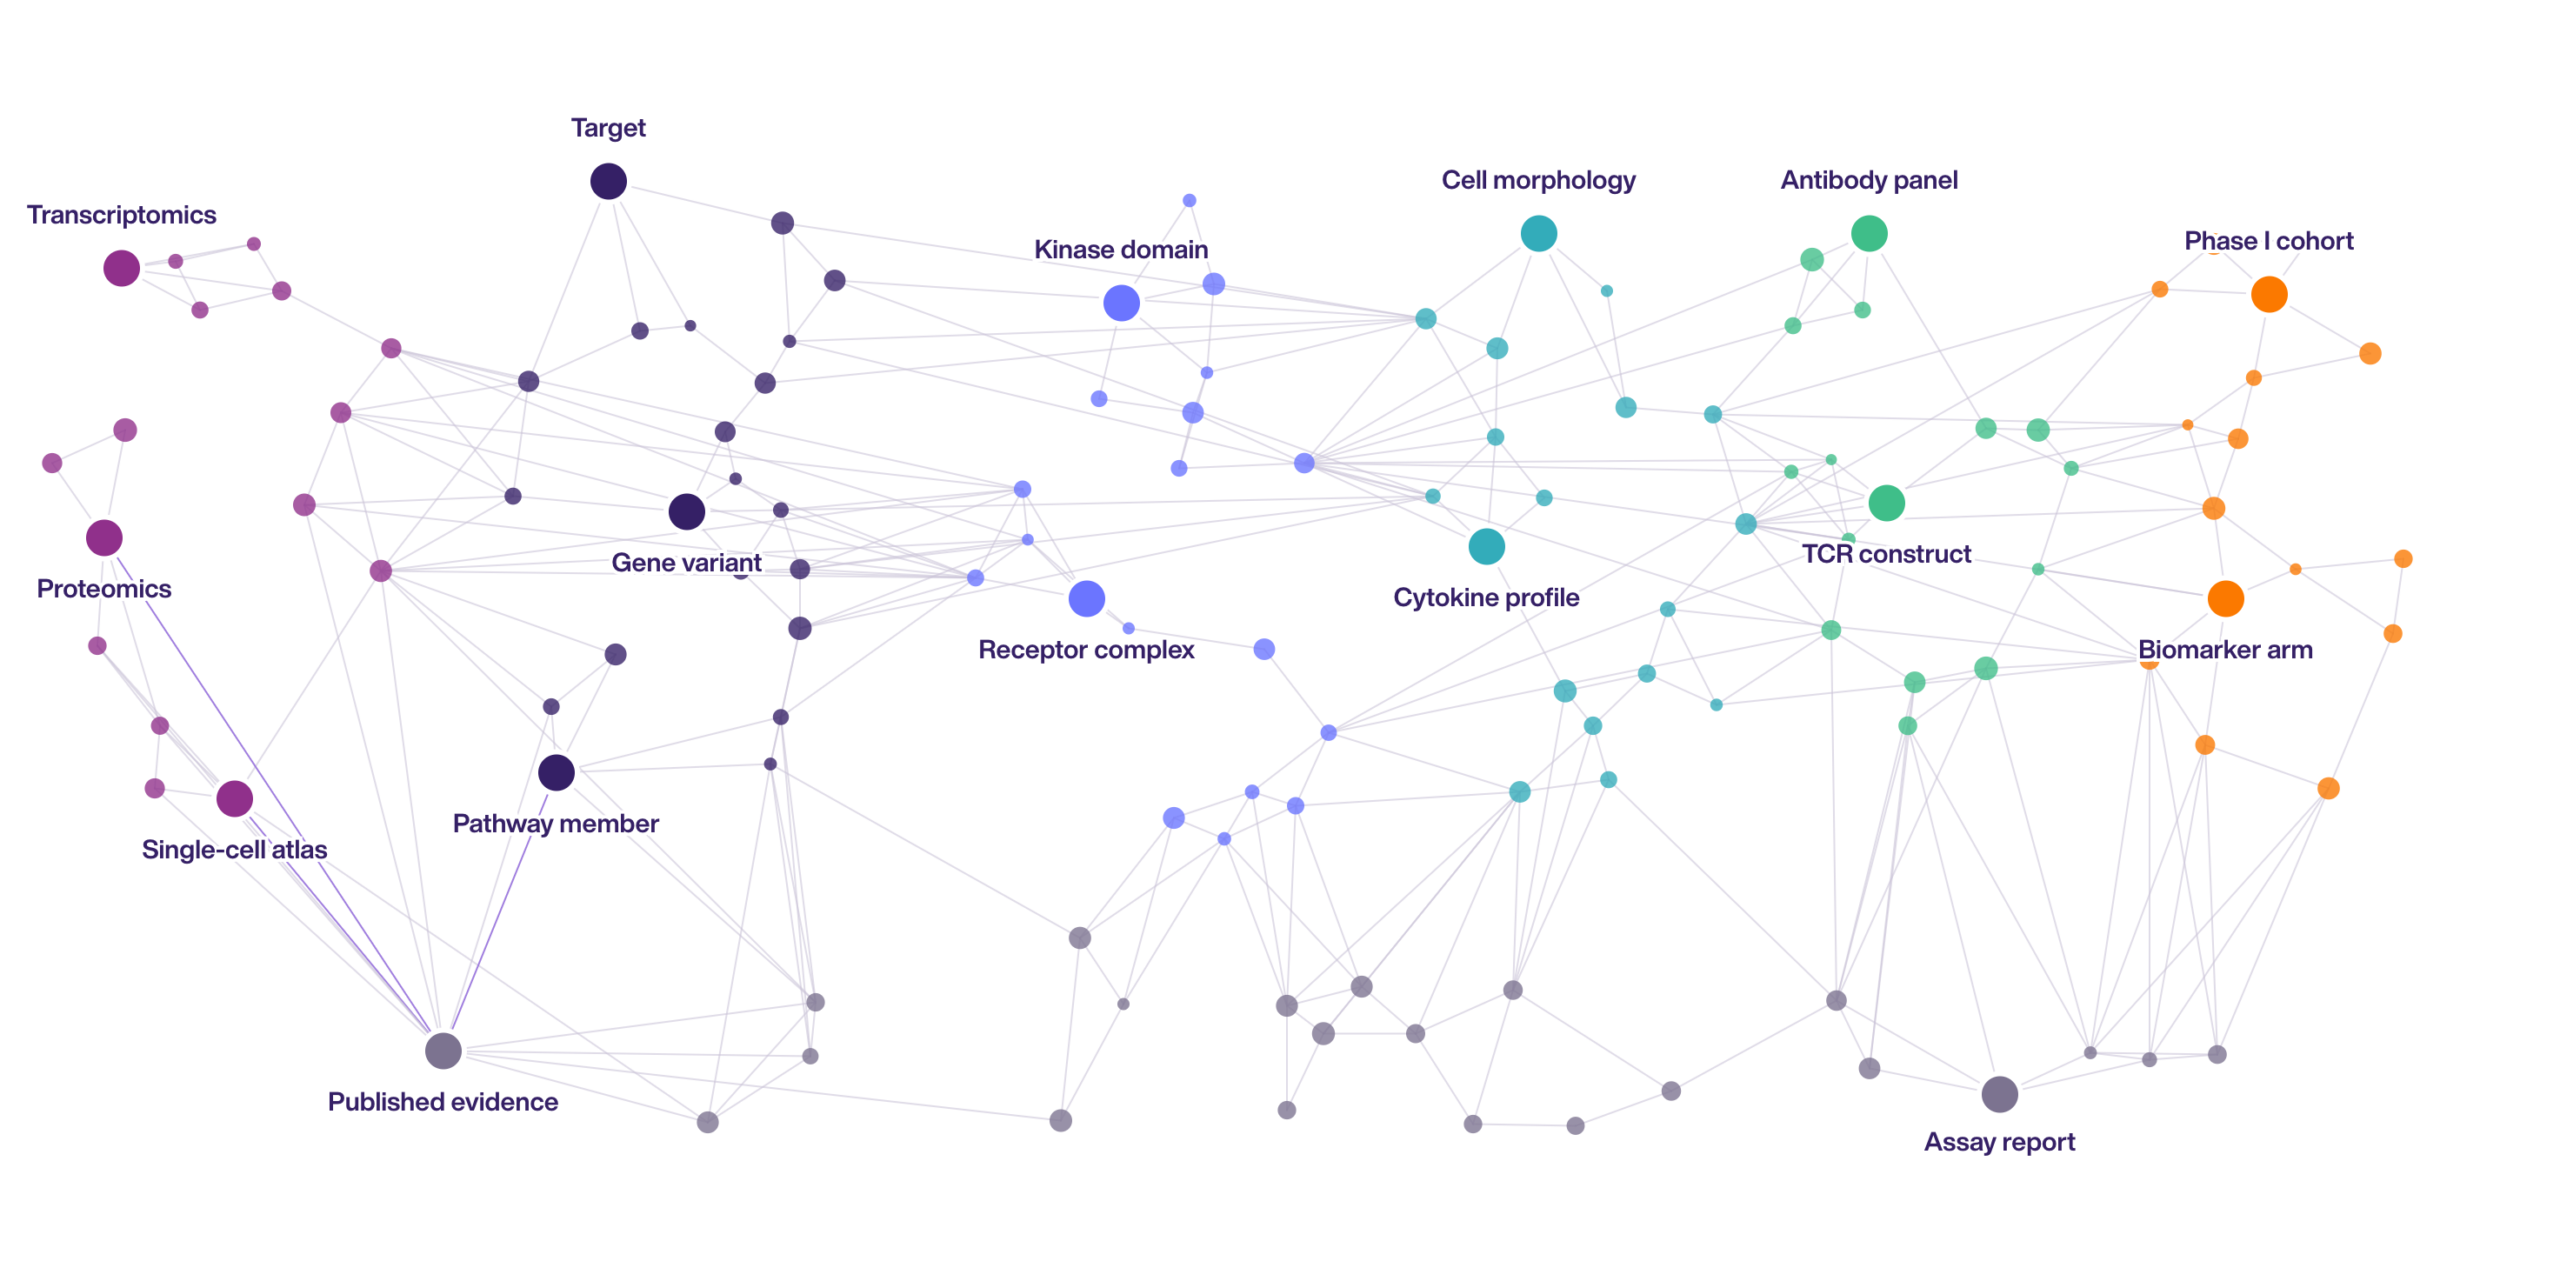
Biomedical data integration and semantic modeling
Knowledge graph implementation starts with consistent representation. Ardigen prepares and connects heterogeneous biomedical data so entities, relationships, evidence, and context can be analyzed together without erasing their meaning or provenance.
Ontology and schema engineering
Identifier harmonization and entity resolution
Map identifiers and resolve entities across proprietary and public sources for consistent representation. Document ambiguities and apply context-specific rules.
Provenance, confidence scoring and data quality
Track evidence sources, transformations, rules, and models. Apply quality controls and confidence logic that support scientific review and preserve uncertainty.
Integration of proprietary and public data
Connect internal assets, experimental data, omics, imaging, and pharmacology to biomedical knowledge. Build reusable pipelines to keep the graph current.

Target prioritization
Combine internal evidence with disease biology, pathways, genetics, literature-derived relationships, and other relevant sources to rank targets with evidence that scientists can inspect.

Indication expansion and drug repurposing
Connect an asset’s mechanism, pharmacology, targets, pathways, phenotypes, and disease associations to explore indication hypotheses beyond the original program context.

Graph analytics and link prediction
Apply graph analytics, knowledge-graph embeddings, graph neural networks, or other appropriate methods to identify patterns and candidate relationships. Select and tune the method to the data, ontology, and evaluation task rather than forcing one algorithm across use cases.

Scientific decision support
Deliver ranked, evidence-backed outputs through tools and workflows that fit how computational and scientific teams review hypotheses, compare alternatives, and document decisions.
Knowledge graph-powered agentic AI in action
From an isolated drug asset to indication expansion intelligence
Challenge
A pharmaceutical team had biomedical knowledge that needed updating and redeployment, while proprietary mechanism-of-action and pharmacology insights remained disconnected from broader biomedical context. The graph needed to support AI/ML and scientific workflows, not only knowledge retrieval.
Approach
Ardigen updated data-ingestion pipelines, redeployed the knowledge graph on premises in a containerized Neo4j environment, aligned the schema and ontology, integrated a proprietary asset layer, and developed proof-of-concept workflows for target prioritization and indication expansion.
Outcome
The engagement produced an operational, reusable biomedical knowledge graph that integrated proprietary assets with broader context and enabled ranked, evidence-backed hypothesis workflows.
Case Study
140k+
13.5M+
20+
10+
4-8 weeks
Entities
Relationships
Internal data sources integrated
Modalities
To a PoC
Why Ardigen is your best partner for knowledge graph implementation
Biology-close, cross-functional delivery
Work with a team that combines drug-discovery context, semantic and data engineering, graph machine learning, and software delivery around the same scientific use case.
Your data, docked to the graph
Adapt proprietary data and internal assets to a flexible semantic layer instead of forcing the question into a fixed product schema.
The right analytical method for the task
Choose and tune graph analytics, knowledge-graph embeddings, graph neural networks, or language-model layers according to the data, ontology, and evaluation objective.
Client-owned environment and IP
Deploy within the client’s environment so integrated data, hypotheses, and tuned models remain under client control.
From initial use case to ongoing operations
Start with a defined scientific question, then create reusable components and operating practices that can support new data, programs, and workflows.
Frequently Asked Questions
What is knowledge graph implementation?
Knowledge graph implementation is the work required to turn a graph concept, proof of concept, licensed knowledge base, or existing graph into a usable system. It can include data audit and integration, ontology and schema engineering, entity resolution, provenance, graph infrastructure, analytics, applications, validation, deployment, and ongoing operations.
How is a biomedical knowledge graph used in drug discovery?
A biomedical knowledge graph connects entities such as genes, proteins, diseases, compounds, pathways, phenotypes, assays, and evidence. Drug-discovery teams can use that connected context for target prioritization, indication expansion, drug repurposing, graph analytics, link prediction, and evidence-backed scientific decision support.
How long does knowledge graph implementation take?
Timing depends on the scientific use case, the condition of the existing graph or knowledge base, data readiness, the number and complexity of sources, deployment constraints, and validation requirements. A focused proof of concept can establish value before broader production rollout; one Ardigen engagement reached a PoC in 4–8 weeks, but that timeframe should not be treated as a universal estimate.
Can an existing knowledge graph be extended?
Yes. Ardigen can assess and extend an existing graph or licensed knowledge base by integrating proprietary data, aligning schemas and ontologies, improving data pipelines, building task-relevant subgraphs, adding graph analytics, and creating interfaces or workflows for defined users.
What data sources can be integrated into a biomedical knowledge graph?
The relevant mix depends on the use case. Implementations can connect proprietary and public biomedical sources, including structured experimental and asset data and other modalities that can be represented with appropriate identifiers, semantics, provenance, and quality controls.
How do knowledge graphs support GraphRAG and AI agents?
Knowledge graphs provide structured entities, relationships, evidence paths, and company-specific context that can guide retrieval for LLM and agent workflows. This supports more traceable, evidence-aware outputs, but it does not remove the need for evaluation, uncertainty handling, and human review.
How should knowledge graph performance and quality be evaluated?
Evaluation should reflect the intended scientific workflow. Relevant measures can include data coverage and freshness, ontology and schema quality, entity-resolution accuracy, provenance completeness, query performance, analytical validation, retrieval relevance for GraphRAG, usability, and maintainability.
Build agentic AI workflows your scientists can test, trace and trust.
See the impact
Case studies

See also:
Contact
Ready to transform drug discovery? Partner with Ardigen
Leave us a message and we will reach out to you within 24 hours, to tell you more about how we can empower your drug development journey.
Newsletter
Become an insider
Be the first to know about Ardigen’s latest news and get access to our publications, webinars and more!