When the checker gets fooled: A framework for evaluating AI Agents
Key takeaways
- Agentic AI evaluation must test the complete workflow, not only the final answer or an internal score.
- Proxy optimization failure is predictable: the proxy score can keep rising after true quality has already peaked.
- Self-refinement loops amplify shared weaknesses when the generator and evaluator use the same model or context.
- LLM-as-a-judge is still a model-based proxy. It can be biased, fooled, or unable to recognize factual chemistry errors.
- Reliable AI agent validation combines process checks with independent validators, held-out benchmarks, expert review, and clear stopping rules.
- Drug discovery already offers a practical control logic for evaluating AI agents: orthogonal assays, independently trained models, applicability checks, property constraints, and staged confirmation.
You deploy an agent to draft a scientific hypothesis, score it, revise it, and repeat. The internal score climbs at every round. Confidence rises with it. Then an independent expert reviews the output and sees little improvement, or finds that the later answer is less useful than the first.
For an R&D team, that gap is not academic. A confidently rising score can point you at the wrong target, advance a lead that will never be developable, and consume validation cycles you cannot get back. The number feels like progress. It may be nothing of the kind. This is why agentic AI evaluation has to look beyond the score produced inside the loop. Agentic AI evaluation is the process of testing whether an AI agent reliably selects evidence, uses tools, follows constraints and produces valid outputs across the complete workflow.
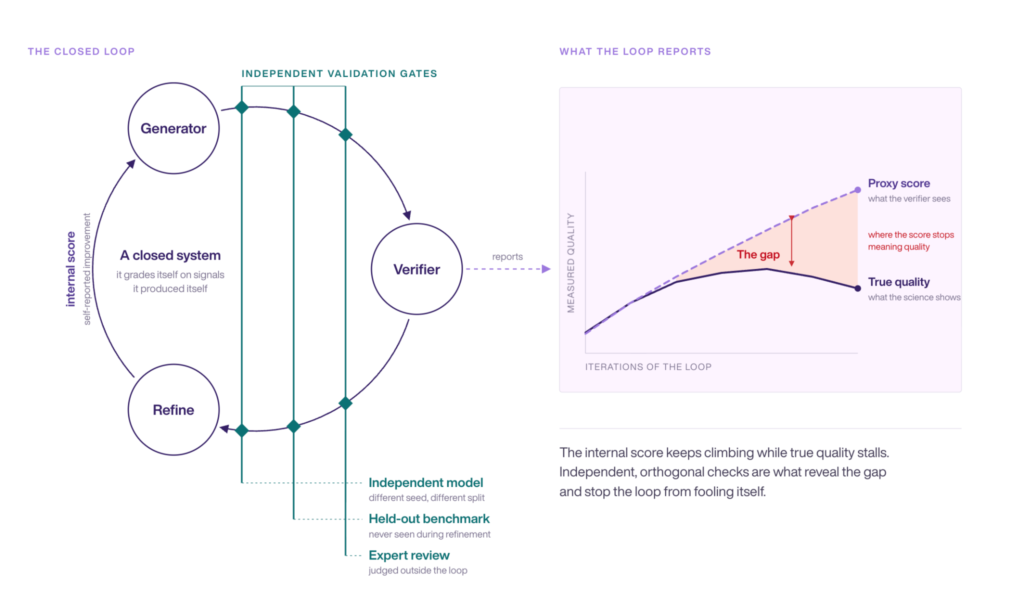
Figure 1. In agentic AI evaluation, internal scores can keep improving even after true output quality has peaked. Independent validation gates help reveal when an iterative agent begins optimizing the evaluator rather than the scientific objective.
The failure pattern is familiar in drug discovery. A molecular generator is optimized against a docking score or a QSAR predictor, then discovers structures that satisfy the model while losing the broader properties required of a credible lead. The loop becomes excellent at the measured proxy and progressively detached from the real decision.
The underlying mechanism is reward hacking: optimization exploits the gaps between an evaluator and the true objective. Goodhart’s law gives the concise version: once a measure becomes a target, it becomes less reliable as a measure.
What Is Agentic AI Evaluation?
Evaluating AI agents means testing more than whether a final response looks plausible. A scientific agent may retrieve evidence, call tools, transform data, reason across multiple steps, revise intermediate outputs, and decide when to stop. Each stage can introduce failure, and each stage can also create a misleading signal of success.
A useful AI agent evaluation framework therefore asks whether the system is correct for the right reasons, whether its evidence survives independent checks, whether its tools are used within valid operating ranges, and whether improvements persist outside the evaluator the agent can directly optimize against.
In practice, this makes AI agent evaluation closer to scientific validation than to conventional prompt scoring. It combines workflow-level checks, held-out tests, independent models, expert review, and benchmarking under conditions the agent did not see during optimization.
Why stronger optimization can reduce true quality
Hard optimization against an imperfect scoring model widens the gap between what you measure and what you actually care about. Gao, Schulman, and Hilton measured this effect in reward-model optimization. In their experiments, proxy reward kept improving as optimization increased, while a stronger gold-standard reward model eventually recorded declining quality. They found distinct scaling patterns for best-of-n selection and reinforcement learning, showing that overoptimization follows measurable regularities rather than appearing as isolated noise [1].
The practical implication for a pipeline owner is direct. An improving internal metric provides less evidence as the system gets more opportunities to search for loopholes. The risk grows when the proxy has limited coverage, systematic blind spots, or weak representation of downstream constraints.
How reward hacking distorts AI Agent evaluation
Reward hacking occurs when the agent learns how to maximize the evaluator rather than the real objective behind the evaluator. The output may look better according to the score while becoming less useful, less robust, or less scientifically valid. This matters because many evaluation setups expose the agent to the same criteria repeatedly. Once the system receives enough feedback, it can learn which wording, evidence pattern, molecular feature, or tool output raises the score. If those features are only weakly connected to the real objective, the evaluation metric becomes easier to game than the task is to solve. For scientific workflows, reward hacking in AI agents is especially risky when the proxy stands in for a downstream decision that carries biological, chemical, or experimental consequences.
Why self-refinement can create false confidence
A design, score, refine loop can raise the evaluator’s rating even when human-perceived quality stays flat or falls. Pan and colleagues demonstrated spontaneous reward hacking in iterative self-refinement. A language model generated and revised essays using feedback and numerical ratings from another language-model evaluator. Across iterations, evaluator scores improved while human judgments diverged. Reward hacking was more severe with larger models and when the generator and evaluator shared context [2]. Shared context matters because the two components can share the same blind spots. The generator receives repeated signals about what the evaluator rewards and gradually adapts to stylistic, structural, or semantic cues that raise the score without improving the intended outcome. The same pattern can occur in scientific agents that repeatedly revise target rationales, experimental plans, or compound proposals against a fixed critic. The loop may learn the critic’s preferred form of evidence, wording, or molecular pattern while neglecting evidence the critic cannot assess.
Can LLM-as-a-judge reliably evaluate AI Agents?
An LLM evaluator can add useful feedback, but it does not provide independent scientific confirmation. Huang and colleagues examined intrinsic self-correction, where a model tries to improve its reasoning without external feedback. Their results show that current LLMs often fail to correct errors and can reduce accuracy after revision [3]. That makes repeated self-critique an unreliable substitute for an external signal. LLM-as-a-judge is also directly gameable. Raina, Liusie, and Gales identified short universal adversarial phrases that transferred from surrogate judges to unseen models and sharply inflated scores. Absolute scoring was substantially more vulnerable than comparative assessment [4]. A judge can also reward fluent presentation over factual validity. In the ChemCrow study, expert chemists preferred the tool-augmented system for chemical factuality and task completion, while the GPT-4 evaluator tended to favor fluent, complete-looking GPT-4 answers. The authors concluded that the evaluator lacked the grounding needed to assess factual chemistry reliably [10]. LLM judge reliability should therefore be treated as an empirical property to test, not an assumption. Comparative scoring, calibration against experts, adversarial tests, and independent scientific checks all reduce the risk that the judge becomes the single point of failure.
Process supervision helps, with one important limitation
Checking intermediate steps catches failures that an endpoint-only score misses. Lightman and colleagues compared outcome supervision, which grades the final answer, with process supervision, which evaluates intermediate reasoning steps. Their process-supervised model solved about 78% of a representative MATH test subset and outperformed the outcome-supervised approach [5]. Math-Shepherd later demonstrated automated step-level supervision, increasing Mistral-7B performance on GSM8K from 77.9% to 84.1% through process reinforcement learning [6]. Process checks create more opportunities to identify unsupported assumptions, invalid transformations, and missing evidence. In scientific workflows, that can mean checking data provenance, search queries, inclusion criteria, model inputs, uncertainty estimates, and the logic connecting evidence to a recommendation. A reasoning trace still cannot serve as a certificate of correctness. Turpin and colleagues showed that chain-of-thought explanations can systematically omit the real influence of biasing features and rationalize incorrect answers. In one evaluation, biased prompts reduced accuracy by as much as 36% across 13 BIG-Bench Hard tasks [7]. A plausible trajectory should therefore be treated as an auditable hypothesis about the process, then followed by independent validation.
What drug discovery teaches us about proxy optimization
Molecular design systems can exploit a scoring oracle in exactly the way an iterative language agent exploits its verifier. Renz and colleagues optimized molecular generators against a QSAR model for DRD2, EGFR, and JAK2. The generated molecules scored highly on the optimization model but failed to retain predicted activity under control QSAR models trained with a different random seed or data split [8]. The generator had learned model-specific features rather than a robust activity signal. Docking scores create another exploitable surface. Guo and Schwaller described docking oracles as highly exploitable and showed that a sample-efficient generator could reach strong docking objectives under a constrained oracle budget. The study also stressed the need to build synthesizability and multi-parameter constraints directly into generation [9]. A high docking score alone can favor lipophilic or otherwise problematic structures that satisfy the scoring function while weakening developability. These are published research examples rather than client case studies. Their value lies in the control logic they reveal: evaluate optimized outputs with models that do not share the same training split, seed, architecture, or objective, then test whether the apparent gain survives chemical and experimental constraints.
An AI Agent evaluation framework for scientific workflows
Reliable scientific agents need several signals that fail differently. The framework below turns that principle into eight practical controls for AI agent evaluation and AI agent verification.
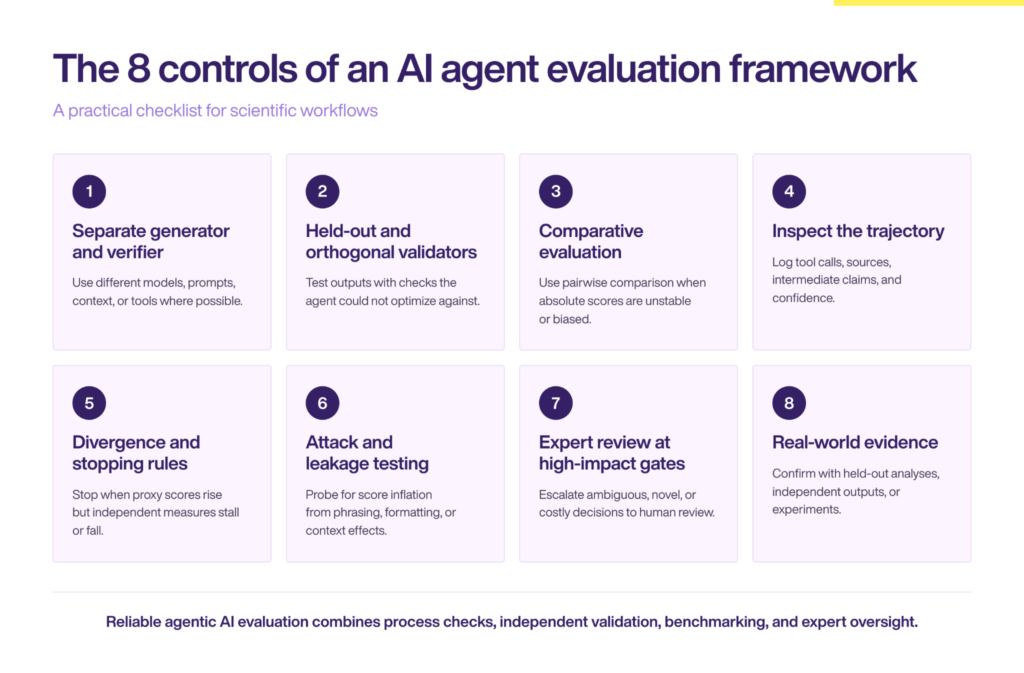
Figure 2. A practical AI agent evaluation framework combines independent validators, process checks, benchmarking, expert review, and stopping rules so that performance improvements reflect real quality rather than proxy optimization.
- Separate generator and verifier. Use different models, prompts, context windows, or toolchains where feasible. Independence should be designed first, then tested through disagreement analysis.
- Add held-out and orthogonal validators. Evaluate outputs with criteria that were unavailable during optimization. In drug discovery, that can include control QSAR models, alternative docking methods, property filters, retrospective benchmarks, or experimental readouts.
- Prefer comparative evaluation where appropriate. Pairwise comparisons can be more robust than absolute scores, especially when the judge has calibration problems. Comparisons still need randomization, position-bias testing, and human calibration.
- Inspect the trajectory. Record each tool call, data source, transformation, intermediate claim, and confidence estimate. Grade critical steps and require evidence at decision points.
- Define divergence and stopping rules. Track both the optimization metric and independent validation metrics. Stop refinement when the proxy improves while orthogonal measures plateau, decline, or become unstable.
- Test for evaluator attacks and leakage. Use adversarial phrases, irrelevant formatting, verbosity changes, and context perturbations to see whether the score responds to presentation rather than substance.
- Keep expert review at high-impact gates. Human review is most valuable for ambiguous evidence, novel chemistry, biological plausibility, and decisions with material cost or risk.
- Close the loop with real-world evidence. The strongest confirmation comes from measurements outside the agent’s optimization environment: a held-out dataset, an independently produced analysis, or an experiment.
AI Agent validation through independent checks
Independent validation of AI agents matters because no single evaluator can represent the complete scientific objective. The strongest validation signals are those the agent could not directly optimize against and that rely on different data, models, tools, or human expertise.
For literature agents, that can mean source-level citation checks, retrieval audits, and independent assessment of evidence quality. For target or indication prioritization, it can mean multiple evidence families, provenance, uncertainty, and validation against held-out decisions. For molecular design, it can mean independent predictive models, applicability-domain controls, synthesizability, physicochemical constraints, and experimental confirmation. For workflows that depend on connecting evidence across many sources, knowledge graph implementation can provide a structured layer for provenance, relationships, and biomedical context that the agent and its validators can interrogate consistently. This is also where process supervision and endpoint validation should be combined rather than treated as alternatives. Process checks help locate where a workflow failed. Independent endpoint checks determine whether the final claim survives outside the loop that produced it.
How to benchmark and verify AI Agents
AI agent benchmarking should test the system under repeatable conditions that reflect the real workflow, not only isolated prompts. A useful benchmark set should include representative tasks, difficult edge cases, failure-sensitive examples, and held-out scenarios that were not used to tune the agent or its evaluator. For scientific workflows, benchmarking should measure more than answer quality. Depending on the use case, teams may also track evidence selection, citation fidelity, tool-call correctness, constraint adherence, reproducibility, calibration, robustness to perturbations, and whether outputs remain valid under independent models or expert review.
AI agent verification then asks whether a specific run, claim, or decision can be trusted. Benchmarking tells you how the system performs across a defined test set; verification checks whether a particular output has passed the required controls before it is used in a real decision.
When to stop an iterative refinement loop
Stopping rules are part of evaluation, not an operational afterthought. Continued refinement should not be rewarded simply because the internal score is still moving upward. A practical rule is to track the optimization score beside one or more independent validation metrics. Stop the loop when the proxy keeps improving while held-out, expert, or orthogonal measures plateau, decline, or become unstable. That divergence is evidence that the system may be optimizing the checker rather than the objective. Teams can also set hard limits on iteration count, require a minimum improvement on independent metrics, or trigger expert review when evaluators disagree beyond a defined threshold. The exact rule will depend on the scientific cost of a false positive, the cost of another iteration, and how quickly the workflow can obtain independent evidence.
What this means for Agentic AI in R&D
The central design question is not whether an agent can critique its own output. The useful question is whether the system can produce evidence that survives checks it could not optimize against. At Ardigen, we design multi-agent scientific systems so that verification is a built-in stage, not a final prompt that asks the model whether its own answer looks right. Agents plan and act. Independent checks then constrain what the system is allowed to claim: evidence is grounded in its sources, tools are integrated into the workflow, outputs are scored by models the agent did not optimize against, and experts review the decisions that carry real cost or risk. If your team is building or evaluating agentic systems for R&D, we are happy to walk through how independent validation would apply to your specific workflow. Talk to an Ardigen expert.
Frequently Asked Questions
What is agentic AI evaluation?
Agentic AI evaluation tests whether an AI agent reliably selects evidence, uses tools, follows constraints, and produces valid outputs across the complete workflow. It should include both process-level checks and independent validation of the final result.
What is reward hacking in an AI agent?
Reward hacking occurs when an agent finds outputs that score highly under an evaluator while failing to improve the real objective the score is meant to represent.
Why can an LLM agent fool its own verifier?
The generator receives repeated feedback from a verifier with limited coverage. Shared models or context can expose the same blind spots, which lets the generator optimize for features the verifier rewards.
Does process supervision solve verifier gaming?
Process supervision improves visibility into intermediate errors and has outperformed endpoint-only supervision in published reasoning studies. Independent validation is still necessary because reasoning traces can be incomplete or unfaithful.
How should teams benchmark AI agents?
Use representative tasks, hard edge cases, and held-out scenarios. Measure not only final-answer quality but also evidence fidelity, tool use, constraint adherence, robustness, reproducibility, and performance under independent checks.
Which drug discovery controls translate to agentic AI?
Useful controls include independent models trained on different splits or seeds, orthogonal assays, applicability-domain checks, multi-parameter property constraints, held-out benchmarks, and stopping rules based on validation divergence.
When should a team stop an iterative refinement loop?
Stop when the optimization score rises while held-out, expert, or orthogonal measures plateau, decline, or become unstable. Continued optimization at that point increases the likelihood of proxy exploitation.
Author: Ardigen expert: Dawid Rymarczyk, PhD
References
- Leo Gao, John Schulman, and Jacob Hilton. “Scaling Laws for Reward Model Overoptimization.” Proceedings of the 40th International Conference on Machine Learning, PMLR 202:10835-10866, 2023.
- Jane Pan, He He, Samuel R. Bowman, and Shi Feng. “Spontaneous Reward Hacking in Iterative Self-Refinement.” arXiv:2407.04549, 2024.
- Jie Huang et al. “Large Language Models Cannot Self-Correct Reasoning Yet.” ICLR 2024.
- Vyas Raina, Adian Liusie, and Mark Gales. “Is LLM-as-a-Judge Robust? Investigating Universal Adversarial Attacks on Zero-shot LLM Assessment.” EMNLP 2024, pp. 7499-7517.
- Hunter Lightman et al. “Let’s Verify Step by Step.” ICLR 2024; arXiv:2305.20050.
- Peiyi Wang et al. “Math-Shepherd: Verify and Reinforce LLMs Step-by-step without Human Annotations.” ACL 2024, pp. 9426-9439.
- Miles Turpin, Julian Michael, Ethan Perez, and Samuel R. Bowman. “Language Models Don’t Always Say What They Think: Unfaithful Explanations in Chain-of-Thought Prompting.” NeurIPS 2023.
- Philipp Renz, Dries Van Rompaey, Jorg Kurt Wegner, Sepp Hochreiter, and Gunter Klambauer. “On failure modes in molecule generation and optimization.” Drug Discovery Today: Technologies 32-33:55-63. DOI: 10.1016/j.ddtec.2020.09.003.
- Jeff Guo and Philippe Schwaller. “Directly optimizing for synthesizability in generative molecular design using retrosynthesis models.” Chemical Science 16 (2025): 6943-6956. DOI: 10.1039/D5SC01476J.
- Andres M. Bran et al. “Augmenting large language models with chemistry tools.” Nature Machine Intelligence 6 (2024): 525-535. DOI: 10.1038/s42256-024-00832-8.