From equation to experiment: How Agentic AI is closing the loop in drug discovery
Key takeaways
- Agentic AI in drug discovery should be judged by the quality of its complete evidence loop, not by the fluency of its final answer.
- Interpretable outputs shorten the distance between computational analysis and scientific review.
- Multi-agent architecture helps only when specialization improves control, evidence access or verification.
- Experimental confirmation validates a specific hypothesis, not the reliability of the whole agentic system.
- The first implementation decision should concern scope and validation, not platform-wide autonomy.
Most AI models used in drug discovery produce a single prediction: a target score, molecular property estimate, response classification or ranked list of candidates. Agentic AI in drug discovery sets out to take on more of the surrounding work by decomposing a research objective, searching literature and databases, calling computational tools, comparing results, revising a hypothesis and proposing a next action.
This expands what AI can contribute, but it also changes the implementation risk. A predictive model can be evaluated against a defined endpoint; an agentic workflow must be evaluated across a chain of decisions, data sources, tools and hand-offs. The question for R&D and informatics leaders is whether the system can produce a traceable, testable and decision-relevant output within the controls of an existing discovery workflow.
Recent research suggests that parts of this closed loop are becoming technically possible, and it also shows why autonomy should be introduced in stages. Many of the systems referenced below are early demonstrations or preprints, so their findings should be read as milestones rather than established, industry-wide performance.
What Agentic AI means in drug discovery
Agentic system. An AI system that does more than answer a prompt or run a predefined analysis. It selects and sequences actions in pursuit of an objective, deciding what to do next based on intermediate results. Depending on the use case, those actions may include:
- searching scientific literature;
- retrieving evidence from a biomedical knowledge graph;
- querying internal databases;
- executing bioinformatics or machine-learning pipelines;
- comparing alternative hypotheses;
- identifying conflicts or missing evidence;
- proposing an experiment;
- analysing returned results;
- updating its hypothesis or next-step recommendation.
AI agents in drug discovery can divide these responsibilities among specialized components: one agent may retrieve literature, another may analyse omics data, and another may evaluate evidence or coordinate the workflow. DrugAgent and PharmaSwarm illustrate how agents can support literature search, knowledge-graph retrieval, prediction, evaluation and candidate ranking [3, 4].
Specialization can improve modularity and make individual steps easier to inspect, but it does not automatically improve accuracy. Multiple agents can repeat the same error, use weak sources or pass unsupported conclusions to one another. The controls around the architecture remain decisive.
How closed-loop drug discovery works
Closed-loop discovery. A workflow in which experimental results feed back into and change the system’s subsequent reasoning, rather than the process ending at hypothesis generation. A useful closed loop connects four functions:
Hypothesis generation – the system proposes a relationship, mechanism or candidate worth investigating.
Evidence evaluation – the hypothesis is examined against appropriate data, literature and computational analyses.
Experimental testing – a wet-lab or otherwise independent test produces new evidence.
Feedback and revision – the result changes the system’s subsequent reasoning or proposed action.
Many systems described as agentic complete only hypothesis generation and evidence evaluation; the loop ends before experimental feedback returns. Generating plausible hypotheses may increase research throughput, but learning reliably from experimental outcomes requires stronger integration, evaluation and governance.
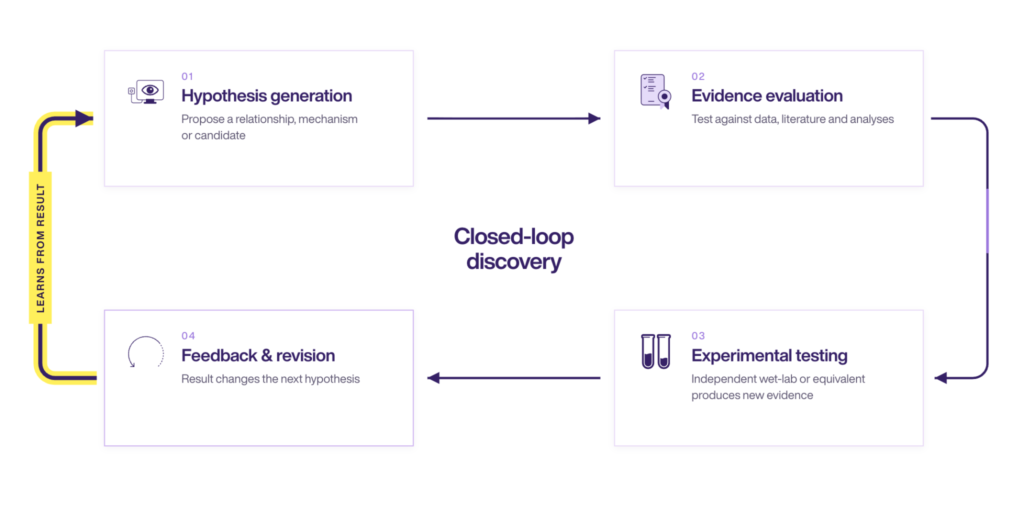
Figure 1. The four stages of a closed-loop drug discovery workflow.
Many systems described as agentic complete only hypothesis generation and evidence evaluation; the loop ends before experimental feedback returns. Generating plausible hypotheses may increase research throughput, but learning reliably from experimental outcomes requires stronger integration, evaluation and governance.
How AI Agents support data analysis in drug discovery
Before an agent can propose or test a hypothesis, it has to work with data. In a discovery setting, agentic data analysis comes down to four repeated actions: retrieving the right data, running appropriate analyses, comparing results and synthesizing the evidence.
Data retrieval. The agent locates and pulls relevant records – internal assay results, public omics datasets, curated knowledge – using approved, versioned sources rather than improvised queries.
Running analyses. In a governed implementation, the agent should call approved bioinformatics or machine-learning tools and record the inputs, parameters and versions used.
Comparing results. It places new outputs alongside prior findings, alternative methods or control analyses to see whether a signal is stable.
Evidence synthesis. It assembles a structured, source-cited summary a scientist can review, rather than a single unexplained answer.
These operations are already performed manually by research teams. The potential value of an agentic workflow lies in coordinating them more consistently and traceably. That value still depends on AI-ready data and realistic testing: omics, imaging and multimodal datasets can contain thousands of variables, sparse biological signal and substantial technical variation. Teams should test whether the workflow selects appropriate methods, detects tool failures, distinguishes technical noise from biological signal and preserves provenance at production-relevant scale. Uncontrolled expansion of candidate transformations can create severe scalability problems [6].
From hypothesis generation to experimental validation
Recent examples show AI-generated hypotheses beginning to reach experimental validation. Influence-Guided Symbolic Regression (IGSR) is useful because it produces an equation rather than an opaque prediction [1]. A large language model proposes candidate mathematical terms, while influence scores evaluate each term’s contribution to generalization performance. This separates proposal from evaluation: candidate structures are selected using an explicit performance signal rather than the model’s verbal judgement.
The resulting equation exposes the variables and weighted relationships for scientific review. Applied to a genomic dataset with 263 features, IGSR surfaced a hypothesis that gene-body DNA methylation
Robin, a multi-agent system for semi-autonomous scientific discovery developed by researchers at FutureHouse, with collaborators from the University of Oxford and Fordham University. It connects literature search and hypothesis generation with experimental planning and the analysis of returned laboratory results [2].In a dry age-related macular degeneration case study, it proposed impaired retinal pigment epithelium phagocytosis as a therapeutic direction and identified ripasudil as a candidate that was assessed experimentally. A separate study reported in-vitro validation of an AI-proposed amyloid-β combination therapy [5].
These are important milestones, but they validate specific hypotheses under defined conditions, not the reliability of agentic systems across discovery programs. The harder implementation task is demonstrating that evidence retrieval, experiment proposal, result analysis, memory and hypothesis updating remain reliable when data and outcomes change.
What Multi-Agent systems add to drug discovery
DrugAgent illustrates how specialized machine-learning, knowledge-graph and literature-retrieval agents can integrate heterogeneous evidence for drug-target interaction assessment [3].
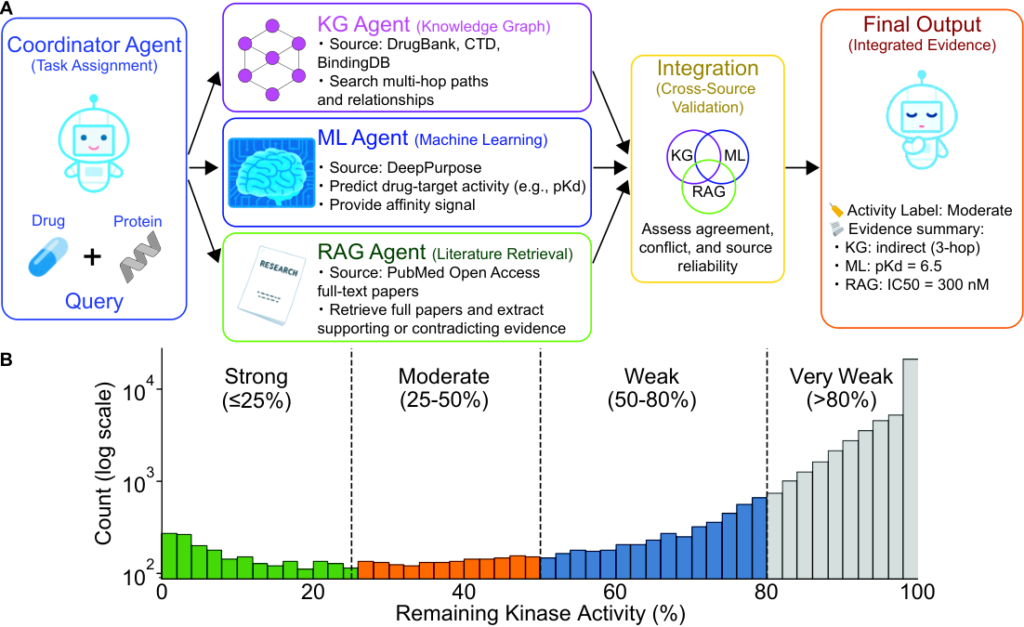
Figure 2. Source: Inoue et al., Figure 1 [3], CC BY 4.0.
What the figure shows. Each specialist produces an independently inspectable signal. The integration step compares agreement, conflict and uncertainty before the reasoning layer produces a DTI assessment with a traceable rationale.
PharmaSwarm describes a broader architecture in which agents support omics analysis, literature mining and candidate generation, followed by simulation and evaluator-led ranking [4].
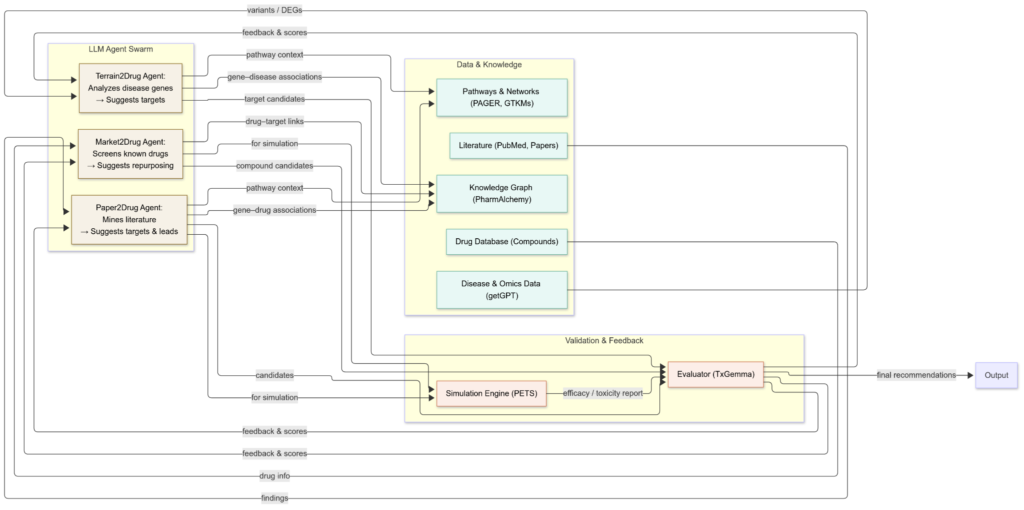
Figure 3.Source: Song, Trotter and Chen, Figure 1 [4], CC BY 4.0.
What the figure shows. Specialized agents generate target and compound proposals from different evidence streams. Simulations and a central evaluator score the proposals, while shared memory and feedback inform the next iteration.
Their practical value lies in orchestration across data sources, scientific tools and review processes. Orchestration is not experimental closure: a system can coordinate tools and produce a coherent recommendation without demonstrating that the recommendation is biologically correct. Evidence level should therefore remain explicit.
Evidence level | What it demonstrates |
|---|---|
Architectural demonstration | The agents can coordinate tasks and tools. |
Retrospective evaluation | The system can recover or rank previously known findings. |
Prospective computational evaluation | The system proposes a new result before the internal answer is known. |
Experimental validation | The proposed hypothesis or candidate is tested independently. |
Repeated closed-loop performance | The system responds appropriately to results across multiple iterations and use cases. |
Table 1. Evidence levels for evaluating agentic AI systems in drug discovery, from architectural demonstration to repeated closed-loop performance.
Most current systems demonstrate one or several of these levels rather than the complete sequence.
Why interpretability does not replace scientific validation
Interpretability helps, but it does not remove the need for validation. A readable equation can still reflect confounding, dataset bias or an incorrectly specified objective. Interpretability lets the research team see and challenge the reasoning structure; it does not establish biological causality. That distinction should shape how teams validate an agentic output. They need to evaluate:
- whether the selected features have plausible biological interpretations;
- whether the relationship persists across seeds, replicates and relevant subsets;
- whether alternative explanations have been considered;
- whether the result generalizes beyond the discovery dataset;
- whether an independent experiment can distinguish the proposed mechanism from competing hypotheses.
Robustness across seeds and replicates, as reported for IGSR [1], contributes to the evidence package but does not replace validation in additional biological settings. Critiques of AI-driven experimental-design systems also show that some agents respond inadequately when feedback changes [7]. A direct test is whether material changes in evidence lead to an appropriate change in reasoning and next action. Trust depends on reproducibility, traceability and falsifiability: teams must be able to determine what the agent used, inferred and executed.
How to evaluate Agentic AI systems before implementation
Before deploying an agentic workflow, informatics teams should assess five connected layers.
Layer | Core question | What to specify |
|---|---|---|
1. Scientific scope | Which single bounded decision will the system support? | Success criteria, acceptable error, human responsibility. “Automate drug discovery” is not evaluable. |
2. Evidence grounding | Which evidence may the system use, and how is provenance established? | Approved sources, versioned databases and ontologies, traceable citations, structured identifiers, separation of observed evidence from generated interpretation, access controls. |
3. Tool & workflow integration | Does it call governed, validated tools instead of improvising code? | Recorded inputs, parameters, version and output for every tool call, so analyses are reproducible independently of the agent. |
4. Validation & feedback | Does the evaluation test the full chain, not just the final answer? | Source-attribution accuracy, tool-selection correctness, run-to-run consistency, response to conflicting or negative evidence, held-out performance, comparison with expert decisions. |
5. Human authority & control | Who is responsible at each consequential hand-off? | Which actions run automatically, which outputs need approval, who can change tools/prompts/data, stop-and-escalate rules, post-deployment monitoring. |
Table 2. Five layers for evaluating agentic AI systems in drug discovery before implementation: scientific scope, evidence grounding, tool and workflow integration, validation and feedback, and human authority and control.
Two layers deserve emphasis. On evidence grounding, a biomedical knowledge graph implementation can connect entities, relationships, provenance and source context in a structured environment for evidence retrieval and comparison. On human authority, review is stronger when scientists approve the evidence, interpretation and proposed experiment as separate objects rather than simply checking a final answer.
To see how connected biomedical entities and evidence can be explored in practice, try the biomedical knowledge graph demo.
Teams should stress-test the workflow with contradictory findings, negative results, incomplete datasets, altered inputs, unavailable tools, conflicting literature and repeated runs from the same starting conditions.
What to test in an Agentic AI proof of concept
The strongest proof of concept is narrow enough to evaluate rigorously but complete enough to expose integration risks.
- Evidence assembly – produce a structured, source-cited evidence package for a previously investigated question; compare it with an expert-curated reference.
- Tool execution – allow a limited set of validated tools; check whether the system chooses appropriate analyses and records reproducible parameters.
- Prospective hypothesis – give a question the internal team has not yet finalized; evaluate novelty, plausibility and evidence coverage before revealing the internal conclusion.
- Feedback response – provide a new result that supports, weakens or contradicts the hypothesis; evaluate whether the system updates its reasoning and next step.
- Experimental hand-off – only after the earlier stages perform reliably should the system propose a prospective experiment or candidate for laboratory testing.
This sequence builds evidence for each capability before increasing the cost and scientific consequence of the agent’s recommendation.
When a simpler scientific workflow is better
Agentic architecture adds value when a task requires dynamic planning, multiple tools, heterogeneous evidence and iterative revision. In the opposite conditions, a conventional workflow may be preferable.
Agentic architecture fits when… | A conventional workflow is likely better when… |
|---|---|
The task needs dynamic planning across steps | The analysis follows a stable, well-defined sequence |
Multiple tools and heterogeneous evidence are involved | Input and output formats are predictable |
Hypotheses are revised iteratively | A validated model already answers the question |
Flexible reasoning outweighs variability cost | Deterministic execution is required |
Reliable data access and tool interfaces exist | The organization lacks reliable data access or cannot support systematic evaluation |
A decision-support application combining structured retrieval, predefined pipelines and expert review may deliver greater reliability with less operational complexity. The objective is not maximum autonomy; it is the appropriate level of automation for the scientific decision.
From promising research to dependable scientific infrastructure
IGSR, Robin and related multi-agent systems show AI participating in a broader portion of the scientific cycle [1–4]. Systems can propose interpretable relationships, coordinate tools and incorporate experimental results. The operational challenge is ensuring that each step uses governed data, validated tools, reproducible pipelines and clear scientific review points.
Dependable agentic systems require more than an orchestration layer. They depend on governed data access, structured biomedical context, validated computational tools, reproducible pipelines and clearly defined scientific review points.
For most organizations, the appropriate starting point is a focused use case rather than an autonomous discovery platform. A first proof of concept should test whether the system uses the right evidence, executes the right tools, responds to feedback and produces an output scientists can review and act on.
For further reading, explore agentic AI development services and consider how the evaluation framework above could be applied to one focused, testable use case.
Frequently Asked Questions
What is agentic AI in drug discovery?
Agentic AI in drug discovery is an AI system that selects and sequences its own actions, searching literature, querying data, running computational tools and revising hypotheses, to pursue a research objective, rather than answering a single prompt or running a fixed analysis.
How is agentic AI different from a predictive AI model?
A predictive model produces one output, such as a target score or property estimate, against a defined endpoint. An agentic system chains together multiple decisions, data sources and tools, so it must be evaluated across the whole workflow rather than a single prediction.
What is closed-loop drug discovery?
Closed-loop discovery is a workflow that connects four functions – hypothesis generation, evidence evaluation, experimental testing, and feedback that revises the next step. Its defining feature is that experimental results change the system’s subsequent reasoning.
How should agent-generated hypotheses be validated?
Treat the hypothesis as something to test, not accept. Check that features are biologically plausible, that the result holds across seeds, replicates and subsets, that alternative explanations were considered, and that an independent experiment can distinguish the proposed mechanism from competing ones.
When is multi-agent architecture justified?
Multi-agent design is justified when specialization improves control, evidence access or verification – for example, separate literature, knowledge-graph, prediction and evaluation agents. It is not justified simply because a task can be split into more steps.
What should informatics teams evaluate before implementation?
Assess five connected layers: scientific scope, evidence grounding, tool and workflow integration, validation and feedback, and human authority. Start with one bounded decision and define validation gates before increasing autonomy.
Author: Ardigen expert: Dawid Rymarczyk, PhD
References
Sources verified August 2026.
- Saveliev, E. S., Holt, S., Seedat, N., Bentley, D. L., Weatherall, J. & van der Schaar, M. Influence-Guided Symbolic Regression: Scientific Discovery via LLM-Driven Equation Search with Granular Feedback. ICML 2026. arXiv:2605.29184. https://arxiv.org/abs/2605.29184
- Ghareeb, A. E. et al. A multi-agent system for automating scientific discovery. Nature 655, 497–505 (2026). DOI: 10.1038/s41586-026-10652-y. Preprint arXiv:2505.13400 (2025). https://www.nature.com/articles/s41586-026-10652-y
- Inoue, Y., Song, T., Wang, X., Kuang, R., Fu, T. & Luna, A. DrugAgent: Reliable Multi-Agent Integration of Conflicting Biomedical Evidence for Drug-Target Interaction Assessment. arXiv:2408.13378, version 5 (2026; first submitted 2024). https://arxiv.org/abs/2408.13378
- Song, K., Trotter, A. & Chen, J. Y. LLM Agent Swarm for Hypothesis-Driven Drug Discovery. arXiv:2504.17967 (2025). https://arxiv.org/abs/2504.17967
- Xu, Q., Soto, C., Shahnawaz, M., Liu, X., Jiang, X. & Kim, Y. Multi agent large language models for biomedical hypothesis generation in drug combination discovery. iScience 28(12), 113984 (2025). DOI: 10.1016/j.isci.2025.113984. https://pubmed.ncbi.nlm.nih.gov/41362614/
- Zhang, T., Zhang, Z., Fan, Z., Luo, H., Liu, F., Liu, Q., Cao, W. & Li, J. OpenFE: Automated Feature Generation with Expert-Level Performance. ICML 2023. arXiv:2211.12507. https://arxiv.org/abs/2211.12507
- Gupta, R., Hartford, J. & Liu, B. LLMs for Bayesian Optimization in Scientific Domains: Are We There Yet? Findings of the Association for Computational Linguistics: EMNLP 2025, 15482–15510. arXiv:2509.21403. https://aclanthology.org/2025.findings-emnlp.838/