From multimodal data complexity to prioritized therapeutic targets
Integrating fragmented biological evidence into a scalable target discovery workflow
Target discovery rarely depends on a single dataset. Clinical and molecular data, existing biological knowledge and emerging evidence all need to be interpreted together before a target can confidently move toward validation.
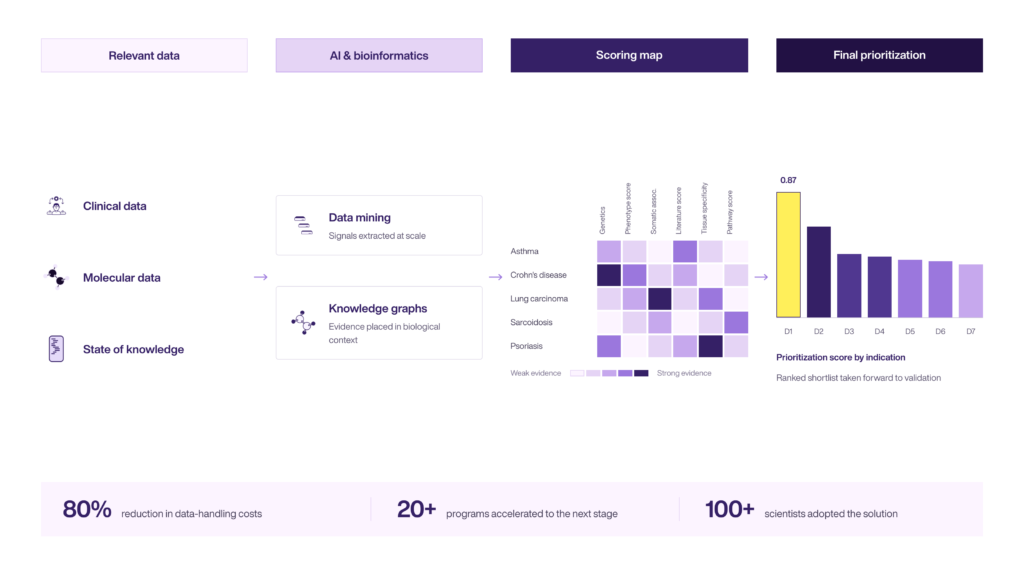
Ardigen built an end-to-end target discovery workflow that integrated multimodal data, applied AI and bioinformatics methods, and used multifactor scoring to rank biological targets. The resulting system gave scientists an interactive way to explore evidence and prioritize targets for downstream validation and drug discovery programs.
The Challenge
Too much biological evidence, too little confidence in what to prioritize
The organization was working with large volumes of heterogeneous biomedical data, but fragmentation made it difficult to convert that evidence into clear target decisions.
Key challenges included:
- Fragmented multimodal data that was difficult and time-consuming to harmonize.
- Weak biological signals obscured within large and complex datasets.
- Biological redundancy making it harder to distinguish the most relevant targets.
- Missing biological context in AI analysis, limiting confidence in computational results.
- Growing data volumes exceeding existing processing capacity.
- Low adoption of AI tools by scientists when results were difficult to explore or interpret in their everyday workflows.
- Additional target-selection questions around multi-target strategies, target accessibility and potential on-target/off-site toxicity.
The challenge was therefore not simply to identify possible targets. It was to create a repeatable way to turn heterogeneous evidence into a defensible target ranking scientists could investigate further.
Our Approach
An end-to-end data to decision journey from multimodal evidence to ranked targets
Ardigen designed a workflow spanning data infrastructure, AI modeling and scientist-facing tools rather than treating target identification as an isolated modeling exercise.
1. Integrate the relevant evidence
Clinical, molecular and other available knowledge sources were brought into a common analytical workflow.
AI-led data ingestion supported scalable development of reusable data products while reducing the burden of repeated manual harmonization.
2. Add biological context
Bioinformatics methods, data mining and biology-oriented knowledge graphs connected individual signals with broader biological relationships and existing knowledge.
This provided the context needed to move beyond simple statistical associations toward more biologically informed target assessment.
3. Score targets across multiple factors
Potential targets were assessed using multifactor scoring, combining evidence into a structured scoring map rather than relying on one signal or data modality.
The resulting ranking helped distinguish promising targets across novel, emerging and established biology.
4. Bring the results to scientists
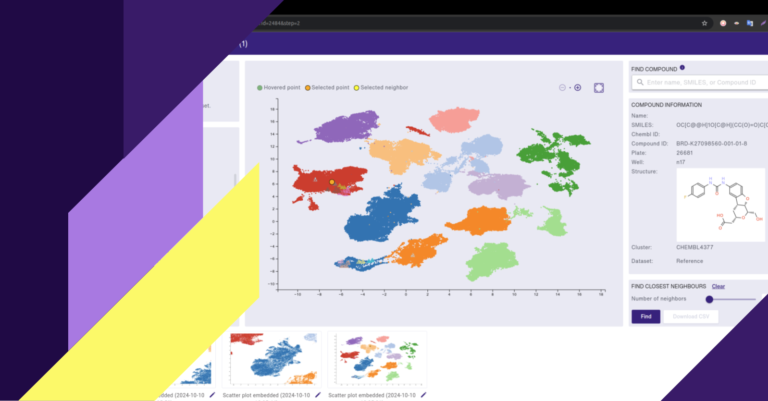
A scientist-facing interface enabled researchers to browse the underlying data and results rather than receiving only a static analytical output.
The architecture was designed to support continued data-to-decision processing as additional evidence became available.
Results
Target prioritization that could move into downstream validation
The project created a scalable path from heterogeneous biomedical data to ranked biological targets supported by multiple lines of evidence.
Key results reported for the implementation include:
- 80% reduction in data-handling costs
- 20+ programs accelerated to the next stage
- 100+ scientists adopted the solution across the organization
- Terabyte-scale multimodal data processed routinely
- First report delivered in approximately 3 weeks
- Ready system implemented in approximately 6 months
Most importantly, the workflow enabled confident prioritization of biological targets for downstream validation and drug discovery programs, while giving scientists direct access to the data and evidence behind the ranking
From target candidates to a decision-ready shortlist
This case demonstrates that target discovery is not only a modeling problem. The quality of the final ranking depends on the entire journey: data ingestion and harmonization, biological context, computational analysis, evidence scoring and the way results are delivered to scientists.
By connecting those elements, Ardigen created an environment in which researchers could move from a broad and ambiguous target space toward a prioritized set of hypotheses ready for further experimental validation.
Discuss your target discovery challenge
Further reading from Ardigen’s Knowledge Hub
- Target Identification: From poor data to quality predictions – a deeper look at the data journey behind target identification.
- Knowledge Graph Operationalization for Life Sciences R&D – how connected biomedical evidence can support target prioritization and other scientific workflows.
- Multi-Agent AI – explore how agentic workflows can help scientists navigate complex biomedical data, evidence and analytical tasks.